Why Transformers Invite Brain Comparisons
When a transformer produces a fluent answer, it is natural to compare it with the brain. Both systems process information in stages, weigh some signals more heavily than others, and use surrounding context to interpret what comes next. A transformer’s attention mechanism especially invites this comparison: it can connect a word with other relevant words, even when they are far apart in a sentence.
That resemblance is useful, but only at the level of function. The model does not have neurons, sensations, goals, or an ongoing stream of experience. Its internal operations are mathematical transformations learned from data. Brain comparisons can therefore highlight shared problem-solving patterns, while also creating confusion if they suggest that a transformer understands or thinks in the same biological sense that people do.
Attention Helps Models Track What Matters
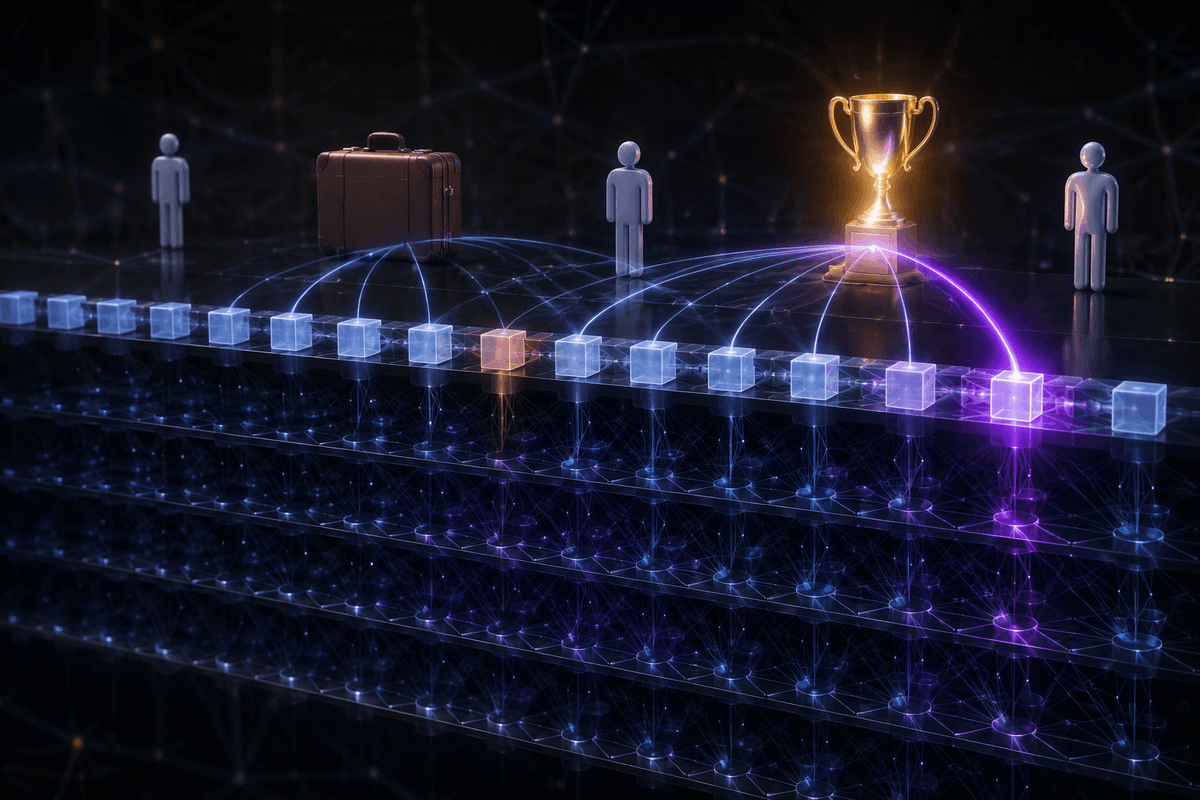
Consider the sentence, “The trophy would not fit in the suitcase because it was too large.” To interpret “it,” a reader connects the pronoun with the trophy rather than the suitcase. A transformer handles a related problem through attention: while processing each word, it calculates which other words provide useful context and gives those relationships greater weight. This helps the model link distant terms, track a topic across several sentences, or use earlier details to shape a later prediction.
The comparison to attention in the brain is helpful because both systems selectively prioritize information instead of treating every signal as equally important. Yet the similarity has limits. Transformer attention is a formal calculation based on learned numerical patterns, not conscious focus or perception. It also does not guarantee that the model has identified the “important” idea in a human sense. Attention can spread across many possible connections, and the resulting output may still reflect statistical associations rather than a stable understanding of the situation.
Layers Build More Complex Representations
When a transformer reads a sentence, it does not form its entire interpretation in one step. Early layers may detect simple relationships, such as word order or nearby grammatical patterns. Later layers can combine those signals to represent broader roles: who performed an action, what a pronoun refers to, or whether a statement expresses uncertainty. Each layer modifies the information passed forward, allowing the model to build increasingly useful representations from the same input.
This layered processing resembles the brain in a limited functional sense. Visual and language systems also transform signals through stages, with later activity often reflecting more complex patterns than earlier activity. The comparison becomes misleading, however, if layers are treated as neatly separated brain regions or stages of conscious thought. Transformer layers do not have fixed jobs in the human sense, and their behavior depends on the task, the training data, and the surrounding network. Adding layers can improve the model’s ability to combine information, but it also increases computational cost and does not guarantee reliable reasoning. Complexity creates capacity, not understanding by itself.
Prediction Connects Language Models And Minds
Imagine hearing someone say, “The restaurant was crowded, so we decided to…” Most readers begin anticipating an ending such as “leave” or “wait.” Language models operate through a related predictive process. Given the words already present, a transformer assigns probabilities to possible next tokens and selects one according to its learned patterns. During training, it repeatedly compares predictions with actual text, gradually adjusting its internal numerical settings. This gives the model a powerful way to represent grammar, meaning, and common associations without storing a simple rule for every sentence.
The brain also uses prediction. Perception is not just a passive recording of incoming signals; expectations help people interpret incomplete speech, ambiguous images, and familiar situations. That functional overlap makes prediction one of the stronger comparisons between minds and language models. But the underlying sources of prediction differ sharply. Human expectations are shaped by bodies, goals, emotions, sensory experience, and consequences. A transformer predicts from patterns in data and has no personal stake in being right. It can produce a plausible continuation while missing the situation’s practical meaning, which is why fluent prediction should not be confused with human understanding.
Memory Works Differently Inside Each System
A person can remember a childhood event years later, connect it with new experiences, and recall it without replaying every detail of the original moment. A transformer’s memory is divided more sharply. During a conversation, it can use information held in its context window, such as earlier questions or instructions, but that working context has a limited capacity. When text falls outside that window, the model may no longer be able to use it directly.
Transformers also contain learned information in their parameters, the numerical settings adjusted during training. This is less like a diary and more like a vast collection of stored patterns. Training can shape the model’s ability to associate names, ideas, and phrases, but it does not create personal episodes with a time, place, or felt significance. Updating those parameters usually requires additional training or a separate memory system, not ordinary conversation. A model may repeat a fact accurately, forget a detail from earlier in a long exchange, or confidently combine related patterns into an incorrect answer. Its memory supports prediction, but it is not autobiographical experience.
Where The Brain Analogy Breaks Down
The differences become clearest when a model must act in the world rather than continue a description of it. A person can combine language with vision, bodily sensations, social cues, personal goals, and consequences. A standard transformer processes the information provided through its inputs and produces a calculated output. It does not feel pain, notice a room, form private intentions, or care whether an answer helps someone. Even when a system is connected to tools or sensors, those additions provide data and capabilities; they do not automatically create a biological point of view.
Brain activity is also shaped by ongoing chemistry, bodily regulation, development, and learning from direct experience. Transformer training is typically separated from use, and its learned patterns can remain stable even when the model generates confident errors. Human reasoning is not always reliable, but it is embedded in needs and consequences that give decisions practical meaning. A model may describe fear, recognize a logical pattern, or recommend caution without possessing fear, understanding in the human sense, or responsibility for the result. The analogy is therefore strongest when comparing information-processing functions and weakest when it implies consciousness, experience, or independent understanding.
A Useful Analogy, Not A Complete Explanation
Comparing transformers with brains works best when it identifies a shared function: both systems can filter information, build layered representations, use context, and generate predictions. Those parallels help explain why transformers are effective at handling language and why their behavior can sometimes resemble familiar aspects of human cognition.
The comparison should stop there unless stronger evidence supports it. A transformer is a designed statistical system, not a smaller version of a person. It lacks a body, personal history, subjective experience, and intrinsic goals. Its abilities also depend on training data, computing resources, context limits, and the quality of its inputs. Brain analogies are therefore useful guides for asking precise questions about information processing, but poor substitutes for explaining consciousness, understanding, or human thought.