Why AI Research Needs a Backward Turn
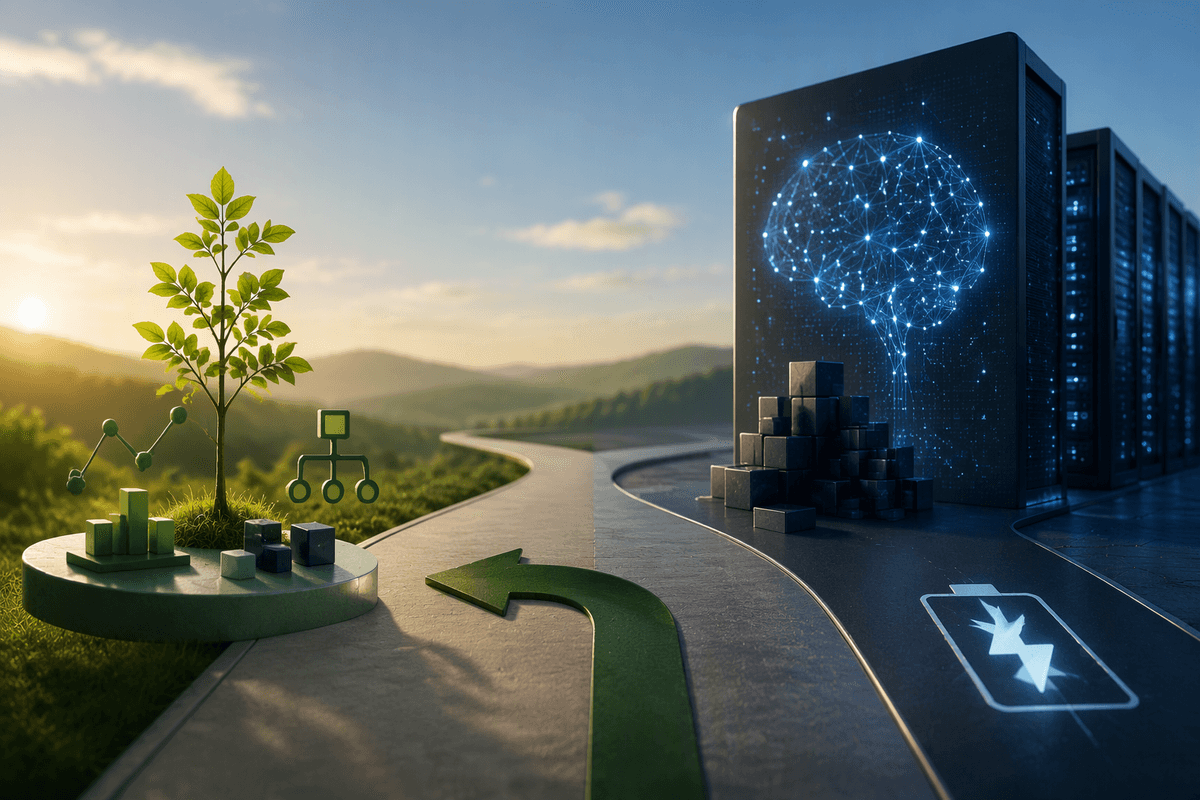
A familiar pattern now shapes AI research: when a model falls short, the first response is often to add parameters, training data, or compute. That approach can improve benchmarks, but it also raises energy use, infrastructure costs, and development time. For many tasks, the extra scale may deliver only modest gains over methods that are easier to train and run.
A backward turn does not mean rejecting modern machine learning. It means reconsidering tools such as smaller models, feature engineering, classical optimization, and task-specific algorithms before treating scale as the default solution. These methods may lack the broad capabilities and flexibility of large systems, and they can require more careful design. Yet when the goal is forecasting, classification, retrieval, or control within a defined setting, their lower resource demands may make them the more responsible starting point.
Scaling Up Is Not the Only Path
Consider a fraud-detection system for a bank. A larger neural network might identify subtle patterns across millions of transactions, but a smaller model using carefully chosen features—transaction frequency, location changes, device history, and unusual amounts—may handle the bank’s main risks at a fraction of the training and inference cost. The simpler approach is not automatically better, but it changes the question from “How large can the model become?” to “What information does this task actually require?”
Scaling remains valuable when the problem involves varied inputs, shifting conditions, or capabilities that are difficult to specify in advance. Large models can reduce manual feature design and transfer knowledge across tasks. They also bring higher hardware demand, longer experimentation cycles, and operational costs that continue after training. Smaller or older methods may need domain expertise, regular maintenance, and separate systems for separate tasks, which limits their flexibility. The practical choice therefore depends on whether added capacity solves a real capability gap or merely improves a benchmark by a narrow margin.
What Older Methods Still Do Well
Older methods remain strong when the problem has clear inputs, stable rules, and a measurable target. Linear models, decision trees, support-vector machines, and time-series techniques can perform well on structured data without learning a broad internal representation of the world. Their smaller memory footprints also reduce inference energy, which matters when predictions run continuously on embedded devices, servers, or large operational systems.
They offer practical advantages beyond efficiency. Their features and decision paths are often easier to inspect, test, and connect to domain knowledge. A forecasting team may improve a compact statistical model by correcting seasonal assumptions or adding a useful variable, rather than rerunning an expensive training pipeline. Reproducibility can also be simpler because there are fewer hardware, software, and tuning dependencies.
Hand-designed features can miss weak or unexpected signals, and separate models may be needed as conditions change. Performance can decline when data becomes unstructured, multilingual, or highly variable. Even so, these methods provide a useful baseline and may be sufficient when the task is narrow enough that general-purpose capability adds cost without adding value.
Measure Energy Alongside Accuracy
Accuracy alone can make a compact model look inferior, even when the difference has little operational value. A useful comparison should record training energy, inference energy, memory demand, latency, and the number of experiments needed to reach the final system. A model that improves accuracy by one percentage point but consumes five times as much electricity may be a poor choice for a service handling millions of predictions.
This accounting is difficult because energy varies with hardware, batch size, software efficiency, data movement, and how often a model runs. Training is only one part of the cost: a modest model deployed continuously can eventually use more energy during inference than a larger model trained once. Researchers should therefore report results across the full system lifecycle and compare them with a meaningful baseline, not just with the newest architecture.
Lower-power methods may sacrifice recall on rare cases, adaptability to new data, or performance on inputs outside the original design. The practical goal is to identify where that sacrifice is acceptable, then reserve larger systems for failures that simpler methods cannot reasonably address.
Choose the Smallest Useful Experiment
Before committing to a larger architecture, teams can test whether the added complexity addresses a specific failure. Start with the smallest model that can represent the task, then define the evidence that would justify moving upward: missed rare events, unstable performance across groups, poor handling of new conditions, or an unacceptable latency target. This turns model selection into a sequence of controlled experiments rather than a race toward the largest available system.
A useful trial might compare a logistic-regression baseline, a tree-based model, and a compact neural network using the same data split and evaluation measures. The comparison should include development time, tuning runs, memory use, inference energy, and performance under realistic operating conditions. If the compact system meets the required threshold, scaling further may add cost without solving a meaningful problem. If it fails, the failure should guide the next investment. The small experiments can expose only known requirements; unexpected capabilities may appear only with broader models. Even so, staged testing limits wasted compute and makes each increase in scale easier to defend.
When Newer Models Still Make Sense
There are cases where a larger or newer model earns its higher energy demand. A translation system serving many languages, a vision model handling varied environments, or a scientific model working across changing conditions may face patterns that are difficult to capture with fixed features and narrow rules. Broader models can also reduce the need to build and maintain separate systems for each task, which may matter when engineering capacity is limited.
The justification should still be specific. A newer model makes sense when simpler alternatives miss important cases, require costly manual adaptation, or cannot meet requirements for robustness and coverage. Its benefits should be measured against the full system cost, including training runs, hardware, deployment, monitoring, and replacement as models or data change. Large models may also introduce longer response times, greater infrastructure dependence, and more difficult evaluation. Choosing one is therefore not a rejection of efficiency; it is a decision that the additional capability solves a problem worth the added resources.
Efficiency Can Become a Research Advantage
Efficiency can improve research quality, not merely reduce its environmental cost. Smaller experiments are cheaper to repeat, easier to audit, and more practical for testing alternative assumptions. That can widen the range of ideas a team explores, especially when compute budgets are limited. A researcher who can run ten focused experiments may learn more than one who spends the same resources training a single large model.
The advantage has boundaries. Compact methods may demand more domain knowledge, careful feature design, and maintenance as conditions change. They may also fail on tasks requiring broad generalization. Still, treating efficiency as a design objective encourages disciplined escalation: use the simplest method that meets the need, measure what larger systems add, and spend extra compute only when it produces capabilities the application genuinely requires.