Why Machines Need Lessons in Fairness
When a bank evaluates a loan application, a hospital prioritizes patients, or an employer filters résumés, an algorithm may influence the outcome before a person ever reviews it. That can make decisions faster, but it does not make them automatically fair. Machines learn from records created by people and institutions, and those records often reflect unequal opportunities, incomplete data, or past discrimination.
Fairness therefore requires more than removing obvious personal details like gender. Other information can act as a substitute, and different groups may be affected by the same system in different ways. Researchers can measure these patterns and redesign models, but they cannot satisfy every fairness goal at once. Improving one outcome may create a new trade-off elsewhere, making fairness an ongoing judgment rather than a simple technical fix.
The Experiences That Shaped Her Questions
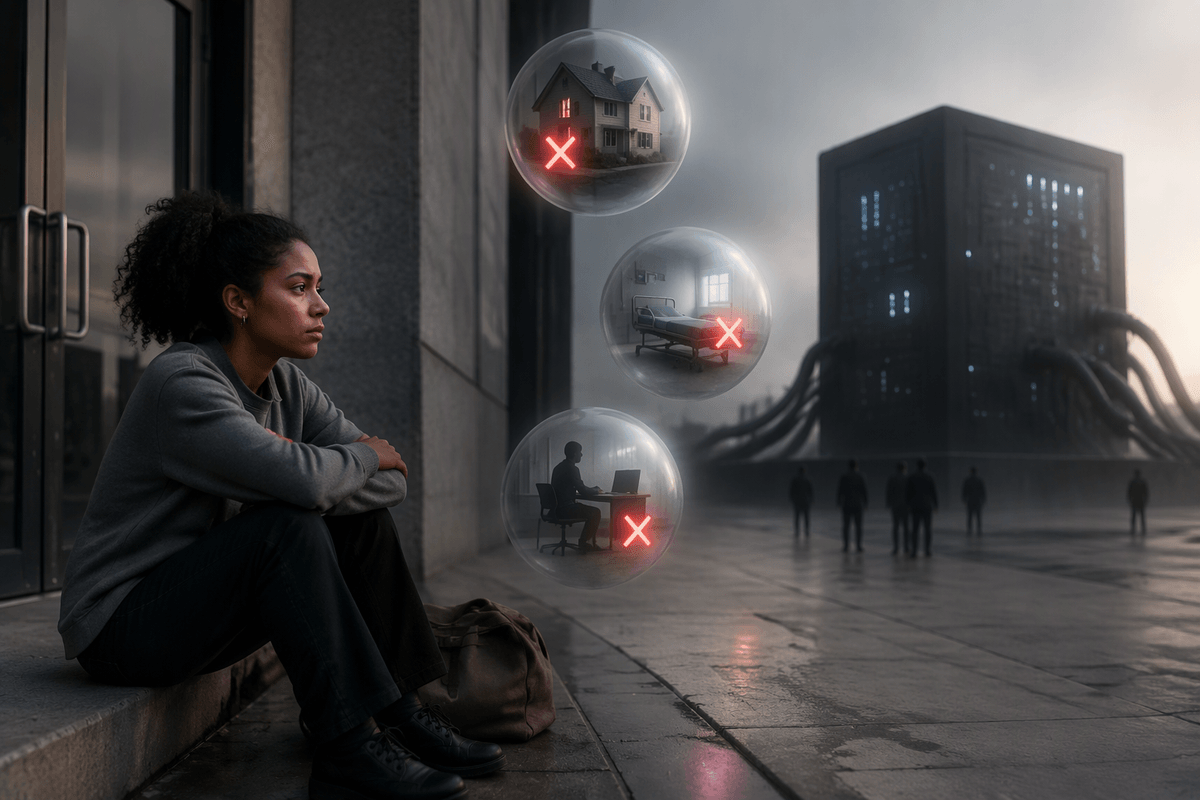
Her questions about fairness began with an ordinary but revealing pattern: technologies often worked smoothly for some people while misreading, excluding, or overlooking others. In classrooms, workplaces, and public services, she saw that a system could appear neutral while reflecting the assumptions built into its data and design. These experiences made “fair” feel less like a mathematical label and more like a question about who receives an opportunity, who faces extra scrutiny, and who has the power to challenge a decision.
That perspective also shaped her view of responsibility. It was not enough to ask whether an algorithm was accurate on average. She wanted to know which groups were represented in the records, how errors were distributed, and what happened when people could not appeal the result. Her work connected technical research with the everyday consequences of automated choices. A model’s calculations might be difficult to see, but its effects could be immediate: a denied loan, a missed diagnosis, or a job application never reaching a human reviewer.
What Does Fairness Actually Mean?
Imagine two applicants receiving the same credit score, even though one group has historically faced lower wages, fewer lending opportunities, or greater scrutiny. Is treating them identically fair, or should the system account for those unequal starting points? Questions like this show why fairness has no single definition. It might mean equal approval rates, similar error rates, equal access to opportunities, or decisions based only on relevant information.
A model might approve loans at the same rate across groups while making more mistakes for one group. Reducing that gap could require different thresholds, which some people may view as unequal treatment. Researchers can also remove sensitive labels from a dataset, yet location, education, or employment history may still reveal patterns linked to them. Fairness measures are useful for exposing these problems, but they do not decide which values matter most. That choice depends on the setting, the harm at stake, and whether people have meaningful ways to question or correct an automated decision.
Teaching Algorithms to Notice Their Bias
A practical first step is to make bias visible before trying to remove it. Researchers can test a model on separate groups, compare approval rates and error patterns, and examine which features most influence its predictions. They may discover that a system performs well overall but fails more often for people with limited medical records, nonstandard résumés, or addresses associated with underfunded neighborhoods. Such testing turns a vague concern into a measurable problem.
Correction can take several forms. Teams might gather more representative data, remove features that add little legitimate value, adjust decision thresholds, or train the model to reduce disparities in its mistakes. They also need to evaluate the system after deployment, because populations and circumstances change. Improving performance for one group can lower it for another, and statistical tests cannot determine whether a feature is ethically relevant. Human review matters, especially when decisions affect housing, employment, health care, or access to credit. The goal is not to create a machine that has settled every moral question, but one whose patterns can be examined, challenged, and improved.
When Fairness Goals Collide
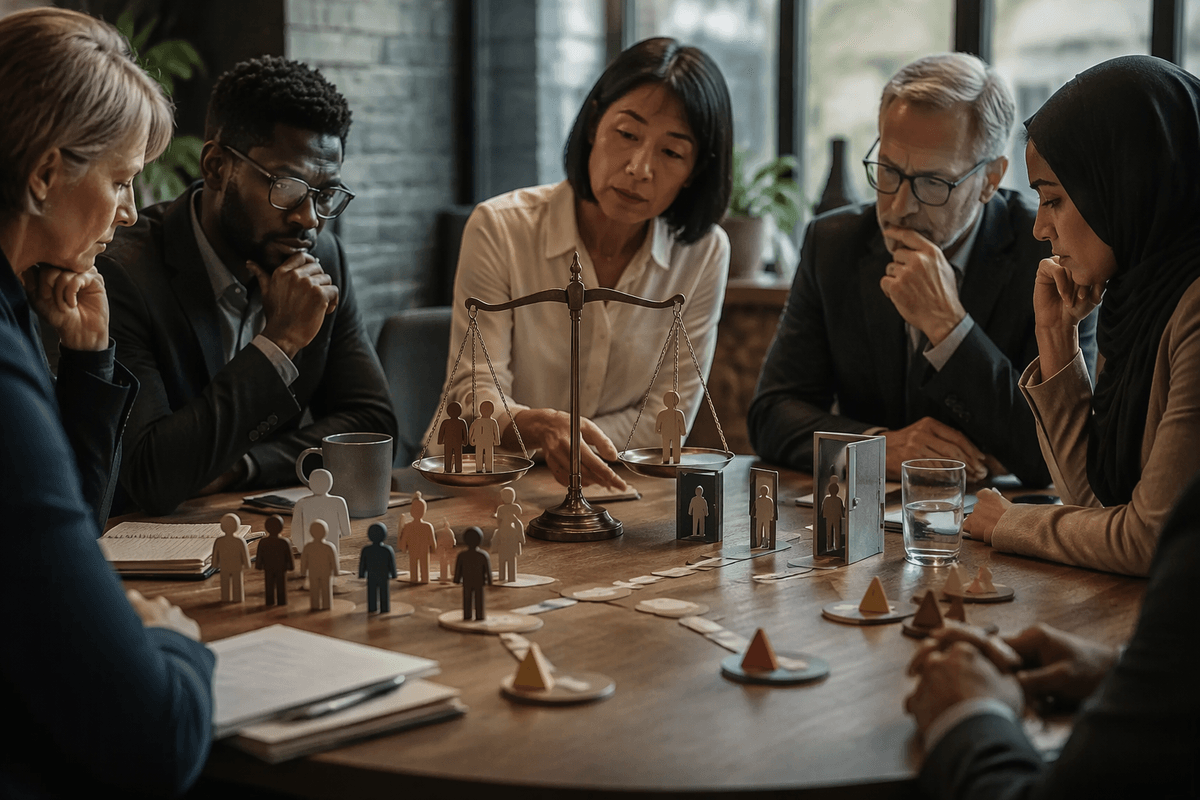
Consider a hiring system designed to reduce unequal outcomes. One approach might set the same acceptance rate for different groups, while another might require the same accuracy or error rate. A model can satisfy one standard without satisfying the others. For example, lowering the score threshold for a group that has been underrepresented may improve access to interviews, but it can also change the balance of false positives and false negatives. Treating everyone by one rule may seem neutral, yet it can preserve disadvantages created before the algorithm was introduced.
These conflicts are not merely technical glitches. They reflect competing ideas about what a fair decision should protect: equal treatment, equal opportunity, reliable predictions, or protection from harmful mistakes. The best choice may depend on the cost of being rejected, overlooked, or incorrectly flagged. A hospital may value avoiding missed diagnoses, while a lender may focus on preventing unaffordable loans. There is also a practical limit: collecting better data, reviewing outcomes, and adjusting models require time, money, and institutional accountability. Researchers can clarify the trade-offs, but communities and decision-makers must determine which risks are acceptable.
From Research Lab to Real Decisions
The fairness test in a research lab can reveal a problem, but real decisions add pressure that controlled experiments cannot capture. A hospital may have to choose between a promising model and limited staff time. A company may resist changing a hiring tool that saves money, even after evidence shows uneven results. Public agencies face another challenge: people may not know an automated system influenced their case, much less how to appeal it. Moving from research to practice therefore requires clear documentation, regular audits, and people responsible for responding when harms appear.
Researchers can help by showing how a system performs across groups and explaining the consequences of different design choices. They cannot guarantee fairness once a model enters an institution with incomplete records, changing populations, or incentives to prioritize speed over review. A system that was carefully tested may still produce unequal outcomes when users apply it in unexpected ways. Responsible deployment means treating an algorithm as part of a larger decision process, with transparency, human oversight, and a workable path for correction. Its value should be judged not only by accuracy, but by whether affected people can understand and challenge its decisions.
A More Responsible Future for Machines
A more responsible future for machines will depend less on finding one perfect fairness formula than on building better habits around automated decisions. Organizations should test systems before and after deployment, document their limits, involve people affected by them, and provide a real way to request review. Independent audits can help, but they cannot replace accountability from the institutions using the technology. A model may be technically impressive and still be inappropriate for a high-stakes decision if its errors are difficult to detect or correct.
Readers should therefore treat claims about “fair” AI as questions, not conclusions. Fair compared with what, measured for whom, and with which trade-offs? Machines can help expose patterns of unequal treatment, but deciding what should change remains a human responsibility. The most trustworthy systems will be those designed to make their effects visible, limit avoidable harm, and remain open to challenge as circumstances change.